Protein Binding Site Analysis Software Is Evolving Beyond Pocket Detection
Published on October 8, 2026
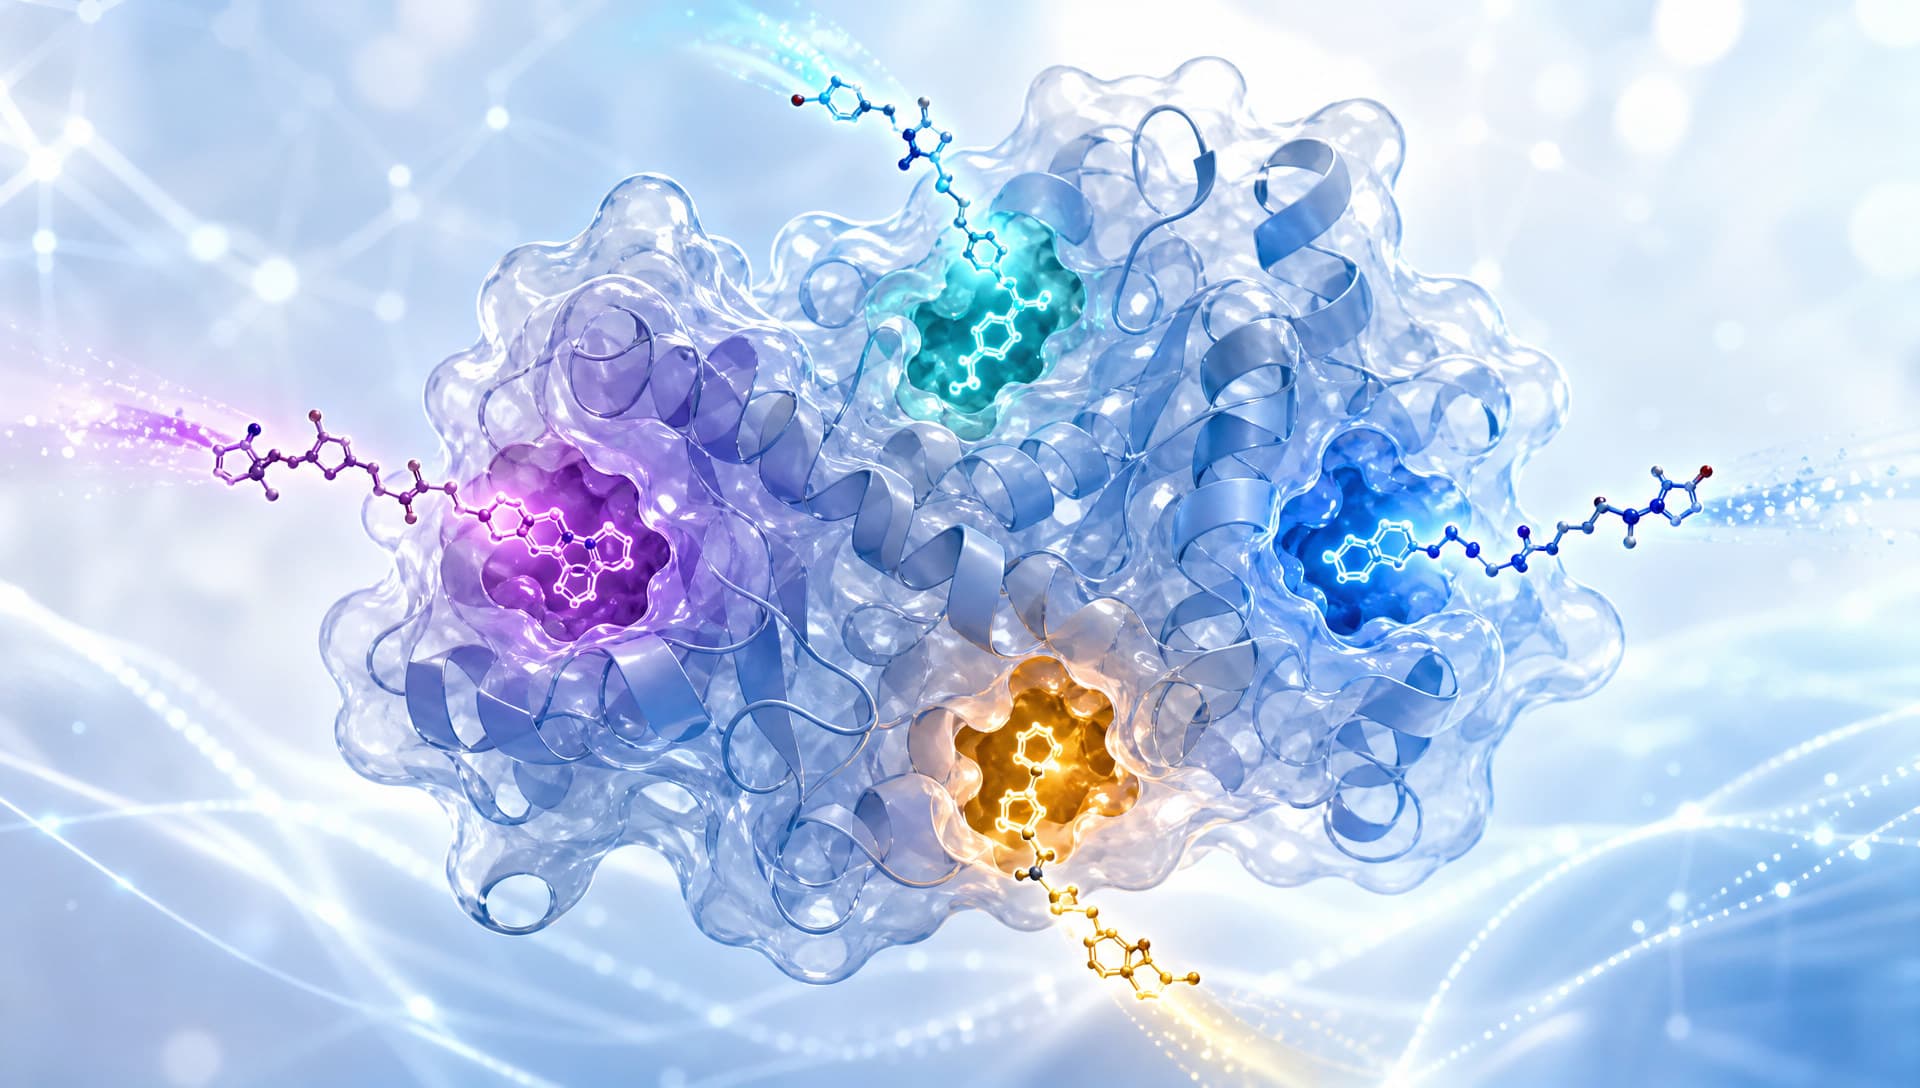
The three-dimensional protein surface reveals several candidate ligand-binding pockets
Category: Structural Biology | Computational Drug Discovery | Protein Engineering
A familiar research problem begins with apparently sufficient data. The team has a protein sequence, perhaps even a predicted structure, yet it still cannot determine where a small molecule should bind, which residues deserve experimental priority, or whether a visible cavity is functional rather than incidental. Different tools return different rankings, and the outputs are split across web pages, tables, and molecular screenshots. The hard problem has shifted from finding software to turning predictions into decisions.
That shift is changing the meaning of protein binding site analysis tool. A useful platform is no longer judged only by how many pockets it detects. It must also help assess input quality, distinguish the type of site being sought, show where independent evidence converges, and prepare results for docking, mutagenesis, or experimental validation.
Why Protein Binding Site Analysis Software Is More Than a Pocket Detector
Binding-site research covers several distinct biological questions. Small molecules, metal ions, nucleic acids, and protein partners place different demands on local shape, electrostatics, hydrophobicity, and residue composition. Orthosteric, allosteric, and transient cryptic pockets may also appear in different conformational states. A deep cavity in one static model is not automatically a functional binding site, while an important site may remain hidden in an unbound structure.
Computational approaches broadly span four technical families: three-dimensional geometry and physicochemical analysis, similarity to known complex templates, traditional machine learning with engineered features, and deep learning that captures sequence or structural context. These approaches are not simple replacements for one another. They provide complementary evidence under different data conditions.
As a result, modern tools are moving from reporting coordinates to explaining sites. Researchers increasingly want to know which residues form a pocket, whether the local structure is trustworthy, whether conserved patterns support the prediction, whether a site persists across conformations, and whether the signal is more consistent with a ligand pocket, a protein interaction interface, or a catalytic region.
Four Shifts Are Reshaping Protein Binding Site Analysis Software
From One Structure to Sequence–Structure Cooperation
Structure-based methods use spatial proximity, surface cavities, and local chemistry directly, making them central to small-molecule pocket analysis. Yet experimental structures are not always available, and predicted structures may be uncertain in flexible loops, disordered regions, or multimeric interfaces. Conservation, family annotation, and protein language models can supplement structural evidence and create a starting point when structural confidence is incomplete.
A mature workflow should not collapse every signal into one opaque score. It should show where sequence and structure agree and where they conflict. A conflict may indicate conformational change, subfamily divergence, or a structural model that needs review.
From Static Cavities to Conformation-Aware Interpretation
Proteins are not rigid sculptures. Ligand-induced fit, side-chain rearrangement, and domain motion can reveal new binding space. Analysis of a single static structure may miss cryptic pockets or overvalue a cavity that is present only by chance.
This is why current workflows increasingly value structural ensembles, comparisons among conformations, and local confidence. Even when software does not run molecular dynamics directly, it should preserve the conclusion that a site may be conformation-dependent rather than presenting one prediction as certainty.

Sequence, structural, and local chemical signals combine to define a candidate site
From Pocket Ranking to Residue-Level Evidence
For molecular docking, a pocket center may be sufficient to define an initial search box. For protein engineering, researchers also need to know which residues contact a ligand, which maintain pocket shape, and which fall within conserved functional regions. Residue-level probabilities, domain position, nearby ligands, and known variants make results more useful for mutational design and mechanism testing.
Structure-based machine learning has shown that local chemical environments on a solvent-accessible surface can be used to assess ligandability. Every model, however, remains dependent on its training data, ligand definitions, and input structure quality. A high score indicates a validation priority, not measured binding.
From Isolated Tools to Traceable Task Orchestration
Binding-site detection is only one component of drug discovery or protein-function research. Upstream work establishes protein identity, structure provenance, and functional annotation. Downstream work may include docking, mutation-effect assessment, expression testing, or binding assays. When these steps are disconnected, residue numbering, chain identity, and evidence level are easily lost during file handoffs.
The ability to preserve task context has therefore become an important software criterion. A traceable workflow should distinguish database observations from model predictions and unresolved unknowns, while retaining the rationale for filtering and parameter choices.
A Decision-Ready Result Has Three Layers
The first is a site map: pocket location, size, exposure, component residues, and spatial relationships to ligands or cofactors. It answers where the site may be.
The second is an evidence map: homolog annotation, sequence conservation, structural confidence, local physicochemical environment, and agreement among methods. It explains why the site deserves attention.
The third is an action map: which pockets can define docking grids, which residues are suitable for mutational testing, which regions should be protected during engineering, and which conclusions require a better structure or laboratory validation. It specifies what should happen next.
When protein binding site analysis software provides all three layers, its output becomes a reviewable research asset rather than an attractive visualization. For project teams, that interpretability can be more valuable than retaining a longer list of low-confidence pockets.
How MatwingsVenus™(protein agent)Connects Binding-Site Analysis to Research Decisions
MatwingsVenus™(晓鹜™)accepts protein R&D objectives in natural language and organizes protein identification, database retrieval from resources such as UniProt and PDB, sequence analysis, structure prediction, and functional-site analysis within one task path. A raw sequence can first be identified and checked against existing evidence. A target with an available structure can move into structure-aware functional-site interpretation. Retrieval-first orchestration helps prevent teams from recomputing a problem that already has a curated answer.
When curated evidence is insufficient and the researcher approves computation, VenusX can perform residue-level prediction for binding sites, active sites, and evolutionarily conserved sites. MatwingsVenus™(protein design agent)separates database-backed observations as Measured, computational outputs as Predicted, and unavailable evidence as Unknown. This evidence hierarchy makes candidate sites easier to review and lowers the risk of treating a model score as an experimental result.
The result can then inform protein engineering. Binding and functional residues may become protected regions, observation priorities, or constraints for mutation design, while structure analysis, mutation-effect prediction, and subsequent validation services can continue the task. The advantage of MatwingsVenus™(晓鹜™)is not that every question is compressed into one click. It is that researchers can see why a task was decomposed, what evidence each stage used, and when human approval is required.

Database retrieval, site prediction, and validation form a continuous research chain
Put the Research Question Before the Feature List
A docking-focused project should prioritize structural input compatibility, pocket geometry, and residue export. Functional annotation of an unknown protein requires template retrieval, conservation, and cross-database context. Protein engineering demands residue-level output that preserves structural relationships. High-throughput programs also need automation, explicit failure records, and reproducible results.
Teams should define validation criteria before running an analysis. Strong protein binding site analysis software does not promise one universally correct answer for every protein and ligand. It helps narrow the search space, expose evidence gaps, and design the next experiment that can distinguish among competing hypotheses.
Conclusion: The Destination Is the Next Executable Decision
Binding-site analysis is progressing from geometric detection to multimodal evidence integration and then to traceable research orchestration. Software worth adopting should connect site identification, residue interpretation, evidence hierarchy, and downstream action. MatwingsVenus™(晓鹜™)links database retrieval, sequence and structural analysis, VenusX functional-site prediction, and protein-engineering pathways in a way that reflects real research: prediction is not the endpoint, but the starting point for the next experimental or design decision.