Protein Pathway Analysis: Does Enrichment Mean Activation?
Published on October 12, 2026
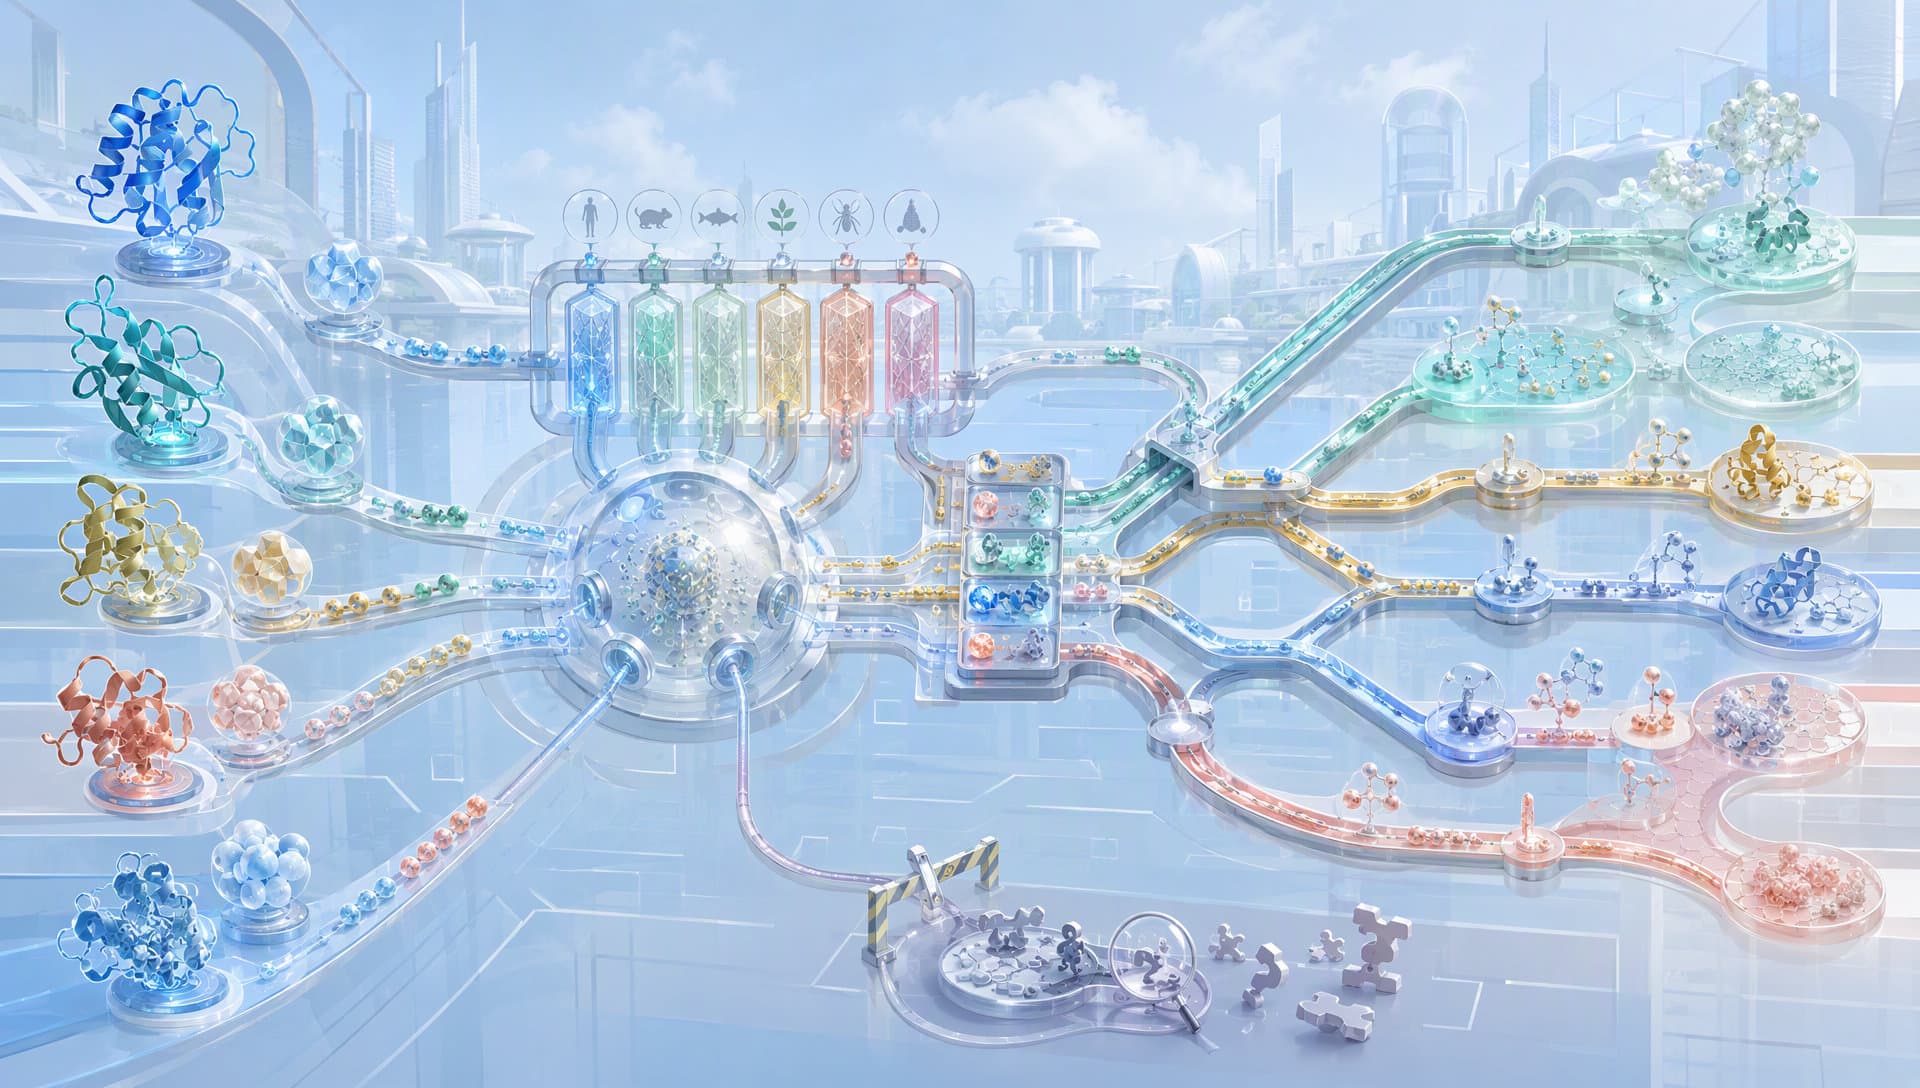
Calibrate protein identity before entering the pathway network
Start by separating two biological questions
Two distinct tasks are often treated as if they were interchangeable. The first asks which documented processes involve a particular protein. The second asks which pathways contain more members of an experimental protein set than expected by chance. The former is primarily a knowledge-retrieval problem; the latter usually requires statistical enrichment analysis.
For one protein, the key issues include species, isoform, cellular location, complex membership, and curated pathway records. For a protein set, the analysis must also account for selection thresholds, the reference universe, hit ratios, and multiple testing. Protein pathway analysis is therefore not a matter of placing names on a network. It begins by defining what is being compared, which knowledge base is being queried, and what kind of conclusion the workflow is allowed to support.
MatwingsVenus®(晓鹜®)can use an intelligent dialogue to capture that question and organize searches across resources such as UniProt, Gene Ontology (GO), Reactome, and KEGG. Its value here is to reduce fragmentation between research tasks and evidence checks. It does not replace curated database records or generate a “proven” mechanism on demand.
The first checkpoint is identifier quality, not bubble size
The same protein may appear as a UniProt accession, a gene symbol, an older alias, or an isoform identifier. A list may also contain mixed species, duplicated entries, and identifiers that no longer map cleanly. Reactome’s analysis documentation describes how submitted identifiers are mapped to pathway entities and emphasizes the need to inspect unmapped entries. If this layer is incomplete, an apparent absence of enrichment may simply reflect failure to recognize the input proteins.
A defensible preparation sequence is straightforward:
1. Confirm the study species and experimental condition.
2. Normalize identifier types while retaining original IDs for traceability.
3. Resolve duplicate proteins, isoforms, and one-to-many mappings.
4. Record successful, ambiguous, and failed mappings.
5. Decide which objects are eligible for the statistical test.
Unmapped entries should not be discarded automatically. They may reflect obsolete naming, incompletely annotated sequences, or genuinely under-characterized signals. With the database-search and protein-sequence analysis capabilities of MatwingsVenus®(晓鹜®), researchers can organize those records by evidence level: Measured for direct observations, Predicted for computational inference, and Unknown where the available evidence remains insufficient. This prevents heterogeneous confidence levels from being presented as one uniform conclusion.
What does significance in protein pathway analysis actually mean?
Over-representation analysis asks whether the submitted list contains more members of a pathway than would be expected under a reference model. Reactome’s tools use a hypergeometric test for this purpose and apply the Benjamini–Hochberg procedure to control the False Discovery Rate (FDR) across multiple tests. A significant result is therefore a statistical enrichment signal first—not a biological on/off switch.
At least four factors should be inspected alongside the FDR:
• Background universe. If an experiment could detect only a subset of the proteome, the background should approximate proteins that had a realistic chance of being observed rather than defaulting to every known protein.
• Pathway size. Very large pathways can absorb many hits, whereas a small pathway may be driven by only a few proteins.
• Hit structure. Several independent reaction nodes carry different information from many subunits of a single complex.
• Database version. Pathway annotations evolve, so analyses performed at different times may not use identical knowledge coverage.
A low FDR can justify prioritizing a pathway for review. By itself, however, it does not show that the pathway is activated, inhibited, or responsible for a phenotype. Increased protein abundance is not synonymous with increased pathway activity: phosphorylation, localization, complex assembly, inhibitors, and substrate availability may control the decisive step.

Interpret significance within its statistical and biological context
Move beyond ranking by restoring direction and topology
A ranked list compresses much of the information needed for biological interpretation. A more informative approach overlays abundance changes, phosphorylation measurements, or other quantitative values onto a pathway diagram. Researchers can then ask whether the observed signal clusters near an entry point, a core reaction, a branch, or a downstream response. Pathway topology can reveal where coverage occurs, but it does not assign a probability that the proposed mechanism is true and cannot substitute for experimentation.
Mixed directions within the same pathway may indicate feedback regulation, cell-population heterogeneity, or a time-dependent response. When hits cluster at a shared upstream module, several significant pathways may be redundant projections of the same underlying signal. If external interaction partners are added to expand coverage, the network also requires caution: the extension may introduce associations that are not manually curated, are condition-dependent, or have uncertain biological relevance.
A disciplined interpretation asks a short sequence of questions. Does the experimental condition plausibly engage this process? Were the key proteins directly measured? Are their directions coherent? Do the hits cover decision-making reactions rather than peripheral members? Is there a simpler alternative explanation? These questions turn a visually appealing story into a testable and falsifiable hypothesis.
A practical protein pathway analysis workflow
A robust workflow does not aim to produce a final biological answer with one click. It reduces uncertainty in stages.
1. Define the comparison. Document samples, treatment, time point, detection method, selection rule, and the observable background. Preserve raw identifiers and software or database versions.
2. Normalize identity. Resolve species, protein IDs, isoforms, and duplicates. Keep a separate list of unmapped and ambiguous objects rather than allowing silent loss.
3. Retrieve documented knowledge. Examine pathway, reaction, and functional records in resources such as Reactome, KEGG, and GO. Keep curated facts separate from computational predictions.
4. Run and audit enrichment. Review hit count, pathway size, FDR, reference background, and overlap among related pathways. Do not promote rank alone into a mechanistic claim.
5. Return to the protein layer. Overlay abundance, modification, localization, domain, or structure information on key nodes. Identify which missing observation would materially change the interpretation.
6. Design validation. Prioritize orthogonal measurements, perturbation experiments, time courses, binding assays, or other context-appropriate tests. Negative results should update the model rather than disappear from the record.
In MatwingsVenus®(晓鹜®), this chain can begin with a single protein or a protein list. The dialogue can organize database retrieval and known functional records, then route selected proteins to function prediction, structure prediction, or deeper literature investigation. Researcher confirmation remains necessary for compute-intensive runs, parameter choices, and high-impact conclusions. The platform connects tasks and evidence; it does not replace experimental judgment.

Network position becomes useful when it guides an experiment
When is the result strong enough to guide the next step?
A decision-ready protein pathway analysis should let a reader answer at least five questions. Are all input objects traceable? Why was this background universe selected? Was significance adjusted for multiple testing? Where do the critical hits occur in the reaction network? Which statements are Measured, which are Predicted, and which remain Unknown?
If these questions cannot be answered, adding more colorful pathway diagrams will not make the interpretation more reliable. Showing unmapped proteins, conflicting evidence, and alternative explanations often has greater practical value because it reveals what the next experiment must resolve. The core output of pathway analysis is not an illustration claiming that a mechanism is complete. It is a prioritized collection of hypotheses that can be tested, challenged, or rejected.
Use pathways as navigation, not as the endpoint
Protein pathway analysis is most useful as a navigation layer. It places dispersed protein changes within documented biological processes and helps researchers identify modules and nodes worth investigating. Enrichment is not activation, connectivity is not causality, and prediction is not measurement. Results become auditable only when identifier quality, statistical boundaries, topology, and protein-level evidence remain visible together.
For projects that need to advance from a protein list to functional checks, structural interpretation, and validation planning, MatwingsVenus®(晓鹜®)provides a conversational entry point for organizing the work. Anchoring each step to database records, labeling evidence as Measured / Predicted / Unknown, and letting experiments answer the decisive questions is a more reliable way to turn pathway maps into research action.