AI Drug Research and Development: Where Does It Create Value?
Published on October 12, 2026
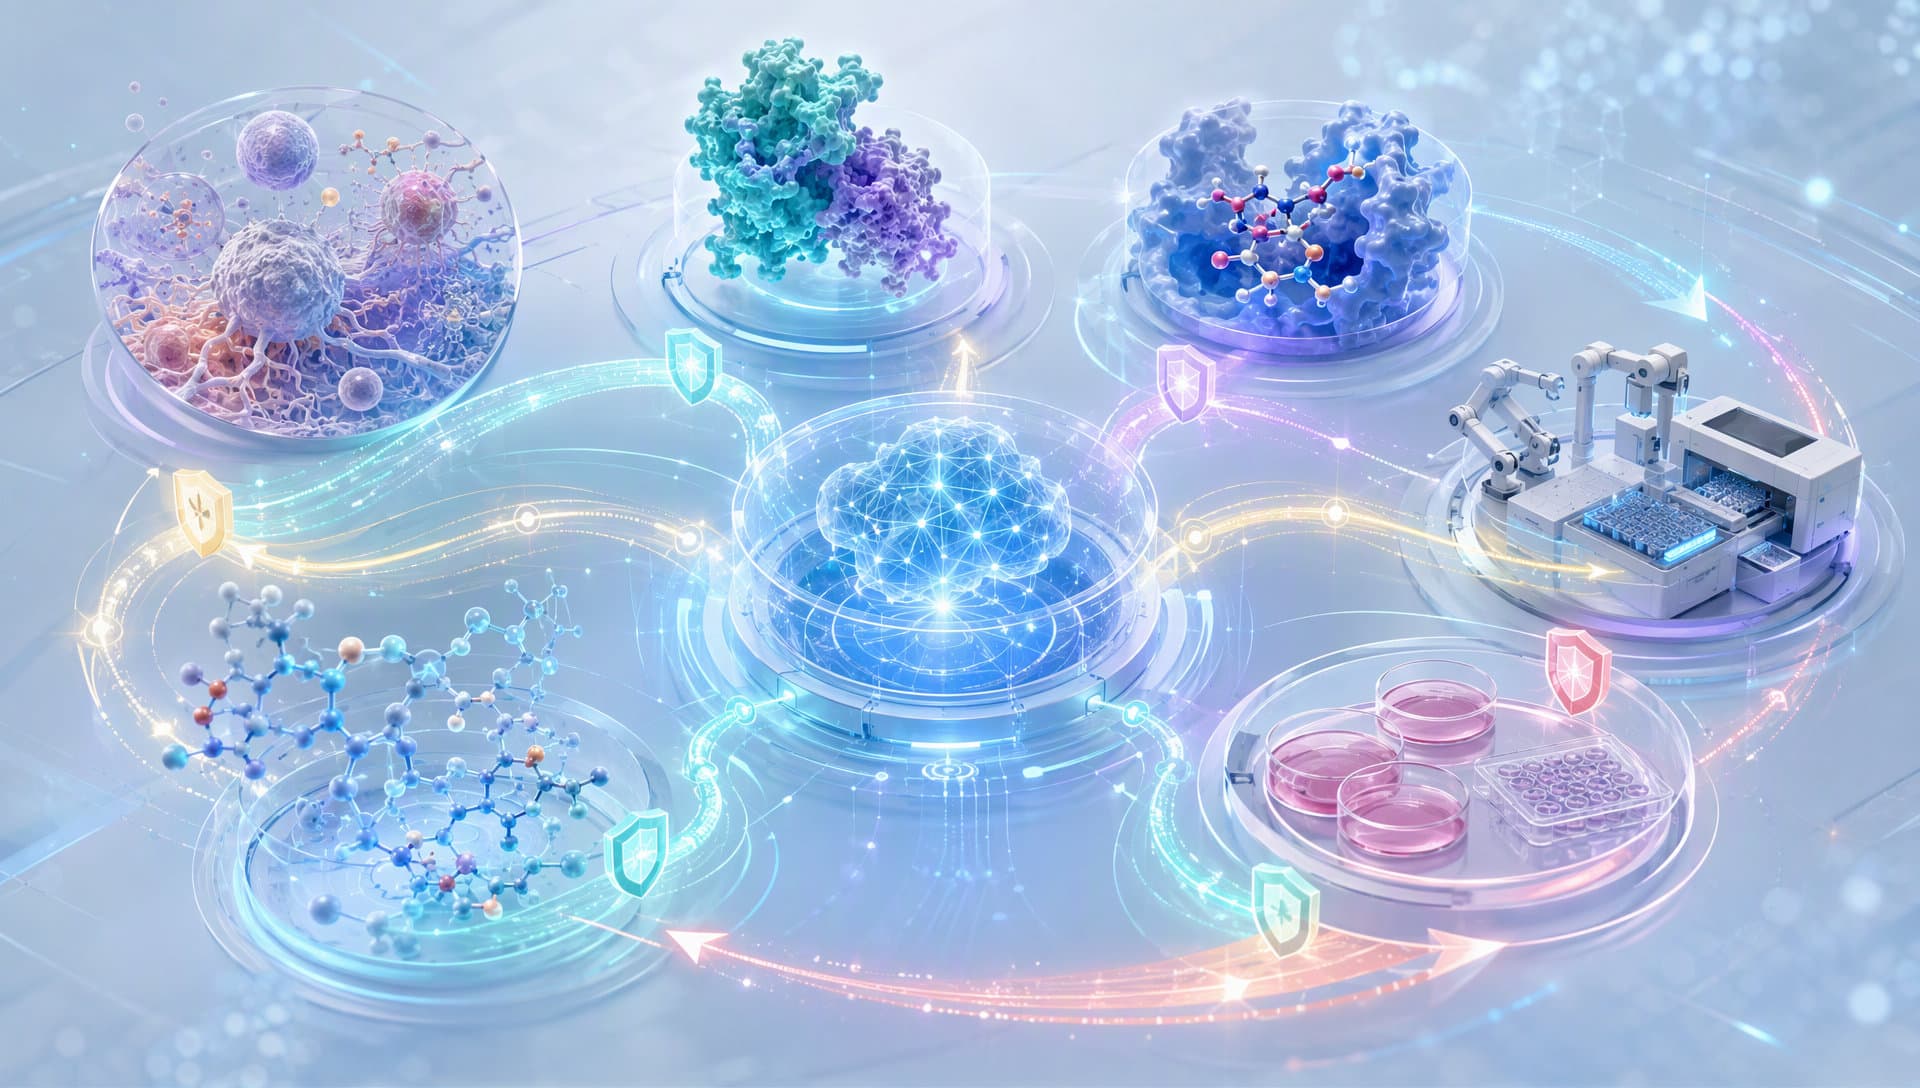
AI becomes useful when it connects decisions to verification
Category: Artificial Intelligence and Drug Development
The model is only one part of the research decision
Drug development is a collection of different problems. Does disease biology support a target? Can a candidate form the intended interaction? Will a designed protein fold and express? Can an experimental result be reproduced? Where should the next unit of time and budget go? These questions require different data, evaluation criteria, and tolerance for error.
A peer-reviewed review describes machine learning as particularly useful for well-specified questions supported by abundant, high-quality data. An official discussion paper likewise describes current and potential AI/ML uses across target identification, candidate screening, nonclinical and clinical research, manufacturing, and safety monitoring, while emphasizing context of use, credibility, and lifecycle considerations. Together, these sources support a practical conclusion: value comes from matching a model to a decision, not compressing the entire pipeline into a black box.
When evaluating an AI drug research and development capability, the first questions should therefore be concrete. What does it accept as input? Which decision does the output support? What happens when it is wrong? Who confirms the next step? How can an experiment update the result?
Data defines where a conclusion is allowed to travel
The same model can behave very differently when the data changes. Measurement conditions, negative-sample definitions, species differences, batch effects, and publication bias all influence what a model learns. If a training set covers only familiar protein families, a high score for an unusual fold or interaction should be treated as a hypothesis requiring validation—not as an established fact.
One useful discipline is to label evidence before interpreting it. Measured identifies direct experimental records. Predicted identifies computational inference. Unknown marks missing evidence or input outside a credible domain. These labels are not a regulatory taxonomy, but they prevent database facts, literature observations, and model outputs from being blended into a single confidence level.
Good data practice also extends beyond cleaning. A reproducible project preserves dataset versions, identifier mappings, sample conditions, selection thresholds, model versions, and failed runs. When a candidate’s rank changes, researchers can then determine whether the cause was new evidence, a parameter choice, a model update, or experimental variation.
Where should AI drug research and development intervene?
Not every step needs a generative model. Four conditions help identify a useful intervention point:
• The task can be specified. Inputs, outputs, and evaluation criteria are explicit.
• The data represents the problem. Training and validation evidence covers the relevant chemical or biological space.
• The result can be tested. Structural, binding, expression, or functional experiments can challenge the prediction.
• Errors can be controlled. Low-confidence or out-of-domain outputs trigger review, fallback, or termination.
When these conditions are present, AI can compress candidate sets, reveal patterns, propose structural hypotheses, or prioritize experiments. When they are absent, the most valuable output may be an evidence gap rather than a forced answer. Detecting insufficient data before an expensive experiment can itself improve a development decision.

Candidates must pass data, model, and validation gates
Convert target research and protein design into a task chain
A credible early-discovery workflow does not begin with a disease name and end with a drug. It connects several smaller decisions.
Define the biological question. Organize disease mechanisms, target function, pathway position, existing intervention evidence, and known risks into a hypothesis that can be supported or rejected.
Search the known space. Query resources such as PubMed, UniProt, and PDB for documented sequences, structures, functions, interfaces, and prior candidates. Generative computation should not replace evidence that has not yet been retrieved.
Expand the candidate space deliberately. For protein-centered projects, researchers may search for natural candidates by function, sequence, or structure. If the known space is inadequate, they can consider engineering an existing protein or designing a new one. Diversity, structural plausibility, expression, stability, and experimental fit matter more than any single score.
Return to the laboratory. Structural confidence is not binding affinity. Computational docking is not functional activity. A generated sequence is not an expressible product. Binding, expression, purification, functional, or other context-appropriate assays convert predictions into new Measured evidence, which can then inform another design cycle.
This decomposition makes the workflow auditable and helps localize failure. A disappointing result may originate in the target hypothesis, data coverage, candidate filter, structural assumption, or assay condition. It need not be reduced to the vague statement that “AI was inaccurate.”
How MatwingsVenus®(晓鹜®)fits protein-centered discovery
The publicly described capabilities of MatwingsVenus®(晓鹜®)focus on protein research and development. Through an intelligent dialogue, the platform can organize database searches, protein-sequence analysis, structure prediction, function prediction, protein discovery, directed mutation design, and de novo design. This makes it relevant to the protein-target, natural-candidate, protein-engineering, and novel-binder portions of AI drug research and development. It should not be generalized to every small-molecule, clinical, regulatory, or commercial task.
Its workflow is retrieval-first. A target is identified and checked against existing evidence before prediction. A discovery task begins by searching curated databases and known sequence or structure space. Compute-intensive mining or generative design follows only when existing options are insufficient and the researcher confirms the objective. Human-in-the-loop (HITL) approval before structure prediction, mining, mutation, or design helps lock inputs, goals, and expected outputs before compute begins.
A de novo protein sequence still requires folding and structural-confidence checks, followed by an experimental plan. Confidence metrics cannot be presented as binding affinity, biological activity, or probability of experimental success. MatwingsVenus®(晓鹜®)can organize these steps as a conversational research chain so that users can see where each candidate originated, which filters it passed, and which evidence is still missing. The product value is research coordination and evidence organization—not an unvalidated efficacy promise.

Experimental evidence turns one prediction into the next design cycle
A credible AI system makes uncertainty visible
Promotional demonstrations naturally highlight attractive candidates, but decision-grade systems must also expose unmapped data, failed sequences, low-confidence regions, and out-of-domain inputs. Researchers should be able to inspect evidence provenance, model versions, parameters, elimination reasons, and experimental feedback instead of seeing only a final ranking.
This visibility clarifies the division of labor. AI is effective at search, synthesis, generation, and large-scale ranking. Researchers define the problem, identify biological exceptions, set stopping rules, and interpret experiments. Human review is not friction added to an automated pipeline; it is the mechanism that places model capability inside a real responsibility boundary.
A mature AI drug research and development workflow can be tested with four questions. Is every result traceable? Are predictions labeled as predictions? Are high-impact transitions approved by a person? Can experimental evidence update the next decision? When all four answers are yes, AI has become part of the research system rather than a standalone demonstration.
Make every computation point to a verifiable next action
The durable value of AI drug research and development is not the production of more candidates. It is the reduction of experiments that add little information. Clear tasks, representative data, explicit evidence levels, human approval, and experimental feedback turn individual model calls into a learning workflow.
For early discovery and design projects centered on proteins, MatwingsVenus®(晓鹜®)offers a conversational entry point that connects retrieval, analysis, prediction, design, and experimental coordination. Let known evidence answer what it can, use models to explore what remains uncertain, and let experiments determine whether a candidate advances. That approach is more reproducible—and more useful—than searching for one apparently universal answer.