Protein Sequence Evolution Analysis: Reading Family Divergence and Functional Origins
Published on September 19, 2026
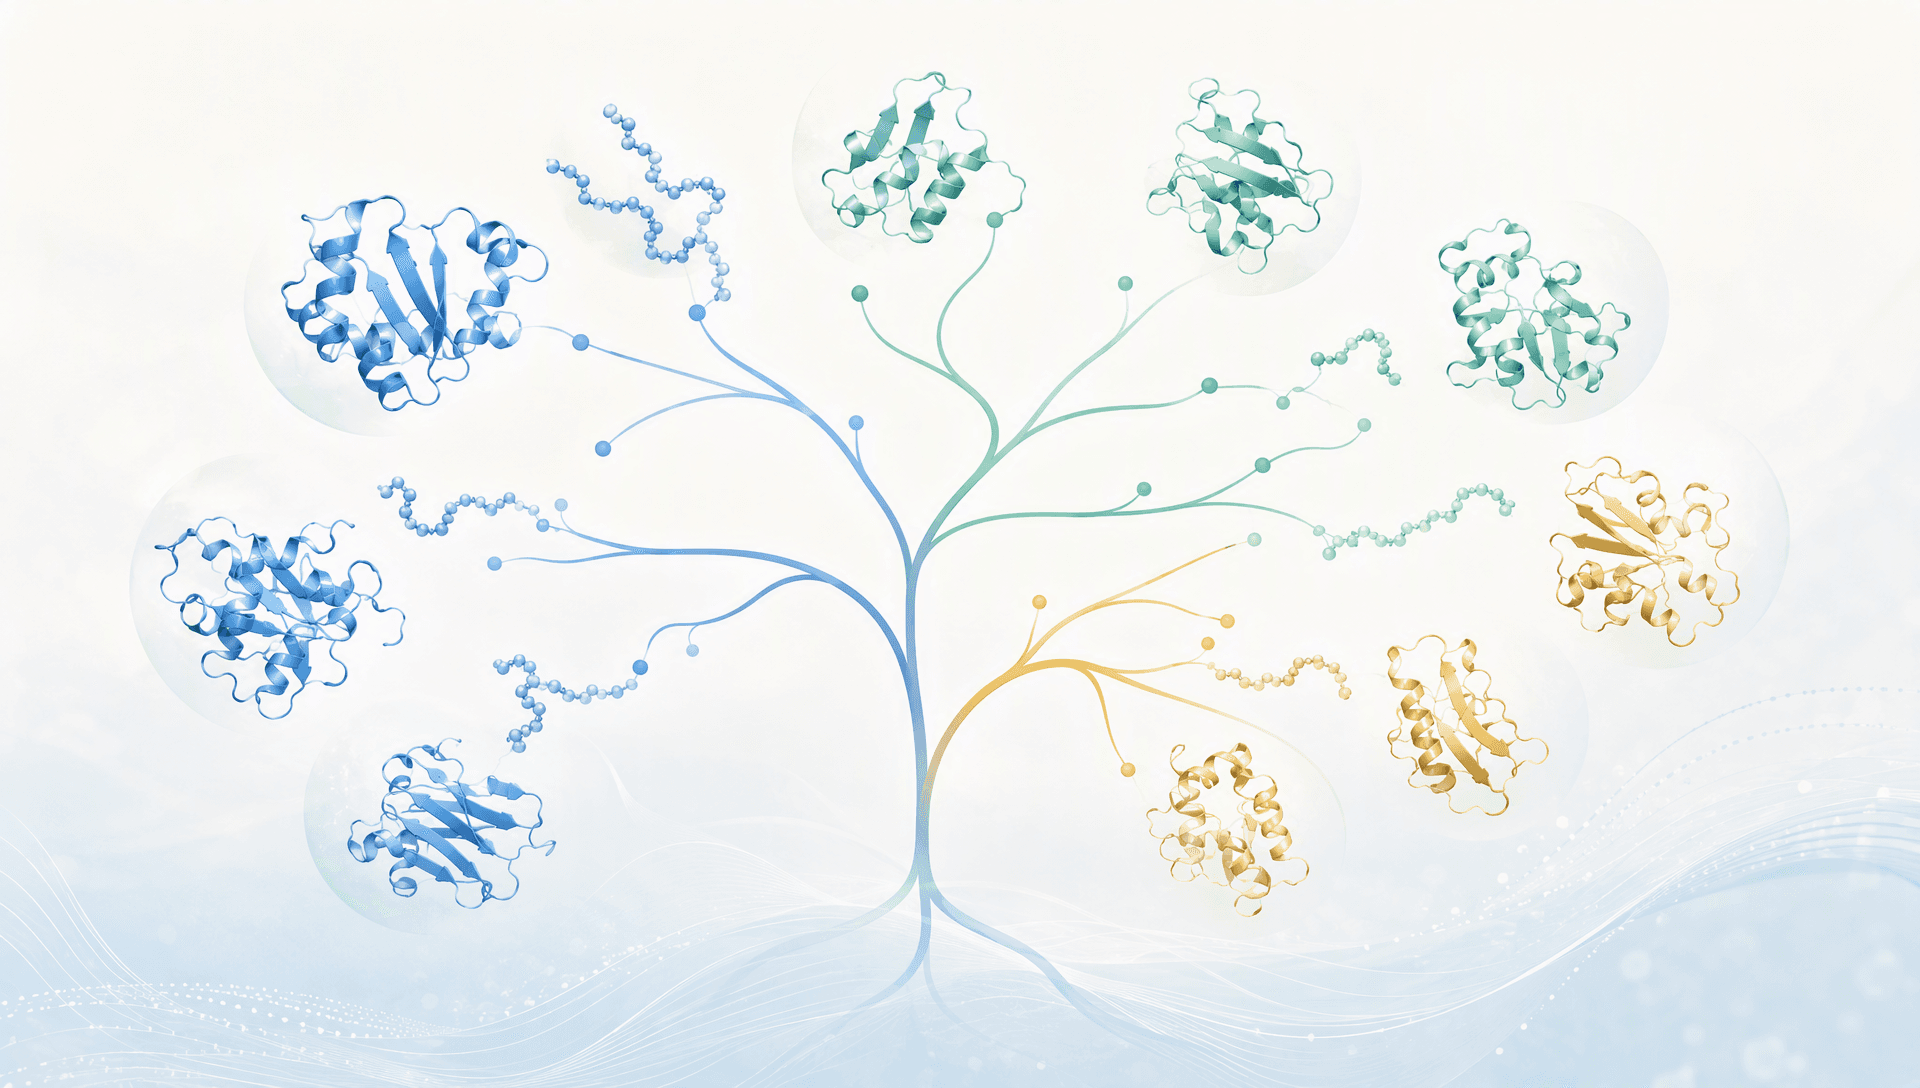
Phylogenetic branches connect protein sequences, structures, and functional change
Category: Molecular Evolution / Computational Biology / Protein Engineering
What protein sequence evolution analysis is designed to answer
Similar proteins may descend from a common ancestor without retaining the same function. Orthologs separated by speciation are often useful for cross-species functional comparison. Paralogs created by gene duplication may progressively divide or acquire roles within a lineage. Selecting only the closest sequence by percentage identity can therefore transfer a derived function to the wrong target.
Protein sequence evolution analysis first reconstructs relationships. Which sequences belong to the same family? Which branches correspond to speciation and which are more consistent with duplication? When was a domain gained, rearranged, or lost? Where do experimentally supported functions appear on the tree? These questions are more decision-relevant than a single similarity score because they determine whether evidence can be transferred responsibly.
A phylogenetic tree is not a decorative family portrait. Branch length, node support, rooting, and sampling all affect interpretation. Two proteins on neighboring tips do not automatically share a substrate, activity, or regulatory mechanism. The tree must be read together with species information, domain architecture, and trusted functional records.
Distinguish homolog types before explaining functional origins

Duplication and speciation events create distinct branches within protein families
Protein family divergence is rarely a uniform stream of substitutions. Duplication can create two copies, one preserving an earlier role while the other changes. Domain rearrangement can place an existing module in a new molecular context. Gene loss can leave different lineages with incomplete historical records. The value of protein sequence evolution analysis is that it organizes these events into testable explanations.
A practical interpretation moves across three layers: tree, domain, and function. First inspect the target’s position and node support. Then compare domain composition, major insertions or deletions, and length changes. Finally, ask whether experimental annotations form a coherent pattern on the relevant branches. If a function occurs only in one paralogous branch, it should not be projected across the entire family. Concordant evidence from related orthologs in independent species generally supports a more defensible transfer.
This perspective also improves candidate discovery. Instead of repeatedly filtering a large pool of similar sequences, identify the branch associated with the desired function and then balance representation, diversity, and experimental practicality within that branch. The resulting candidate set is easier to explain and better suited to structural comparison, property prediction, or validation.
Read changes from the tree without turning inference into fact
A phylogeny represents relationships supported under a particular dataset and model; it is not a recording of historical events. Sparse sampling, inconsistent alignment regions, long branches, and incorrect annotations can alter the topology. A robust protein sequence evolution analysis keeps uncertainty visible: strongly supported nodes can define working groups, weak splits remain provisional, and conflicting methods should trigger a review of sequence boundaries and sampling.
It is also important to separate event mapping from causality. An amino-acid change located on the same branch as a functional transition is historically correlated with that transition, but does not by itself prove causation. A better approach combines branch-specific changes with structural position, known mechanism, and experimental observations to produce a short list of prioritized hypotheses.
Reports can label database and experimental observations as Measured, tree-based ancestral states and functional transfers as Predicted, and conflicting or poorly covered conclusions as Unknown. This preserves the usefulness of evolutionary inference without allowing it to outrun the evidence.
Ancestral sequences make the origin of function experimentally approachable

Modern sequences converge through a time tree into an experimentally testable ancestor
Ancestral sequence reconstruction moves protein sequence evolution analysis from “who is closest” toward “how change may have occurred.” Modern sequences and phylogenetic models are used to infer ancient sequences at key nodes. Biophysical, biochemical, or functional characterization can then compare ancestral and descendant proteins to examine how historical substitutions relate to activity, conformation, binding specificity, or assembly.
The method can divide a long evolutionary trajectory into experimentally testable stages, but its boundary is equally important: an ancestral sequence is a model-based inference, not a directly recovered ancient sample. Tree structure, substitution model, and site-level uncertainty should be recorded. Important conclusions should ideally be tested across multiple plausible reconstructions rather than relying on one maximum-probability sequence.
For protein engineering, an ancestral perspective offers a different design language. Instead of asking only which present-day position to change, researchers can ask which historical combinations helped shape the current function. That framing reduces the risk of interpreting a mutation outside its sequence background and can suggest context-aware routes for combinatorial design or functional transfer.
How MatwingsVenus™(晓鹜™)connects evolutionary analysis tasks
A strong protein sequence evolution analysis often spans database retrieval, identity checks, homolog search, sequence curation, phylogenetic interpretation, and downstream validation. The official MatwingsVenus™(晓鹜™) website describes protein sequence analysis, database retrieval, and conversational research workflows, with access to sources including UniProt, NCBI, PDB, and PubMed. Its sequence-search context also includes BLAST and MMseqs2 as entry points for collecting candidates and defining an initial family scope.
A researcher can begin by providing MatwingsVenus™(晓鹜™) with the target protein, the evolutionary question, and the desired taxonomic range. Identity checking and homolog retrieval can then establish a candidate set, after which orthology, paralogy, and domain boundaries should be confirmed by the researcher. The same task context can continue into natural-protein discovery, structural comparison, or protein-engineering planning, reducing evidence loss between disconnected tools.
The platform’s role is not to automatically declare an evolutionary story. Its value is to organize retrieval, analysis, and R&D actions into a traceable chain. Computational steps should have explicit inputs, parameters, evidence levels, and validation plans, consistent with the retrieval-first and confirmation-based workflow used by MatwingsVenus™(晓鹜™).
Conclusion: turn similar sequences into directional R&D evidence
Protein sequence evolution analysis elevates sequence resemblance into a structured interpretation of family history, functional divergence, and ancestral states. Reliable conclusions come from cross-checking homolog type, phylogeny, domain architecture, and functional evidence rather than trusting one tree or one identity value. By connecting database retrieval, sequence search, and downstream research tasks through MatwingsVenus™(晓鹜™), researchers can build a clearer evidence chain and convert evolutionary inference into specific, testable next steps.