How to Predict Enzyme Function from Protein Sequence with Confidence
Published on September 16, 2026
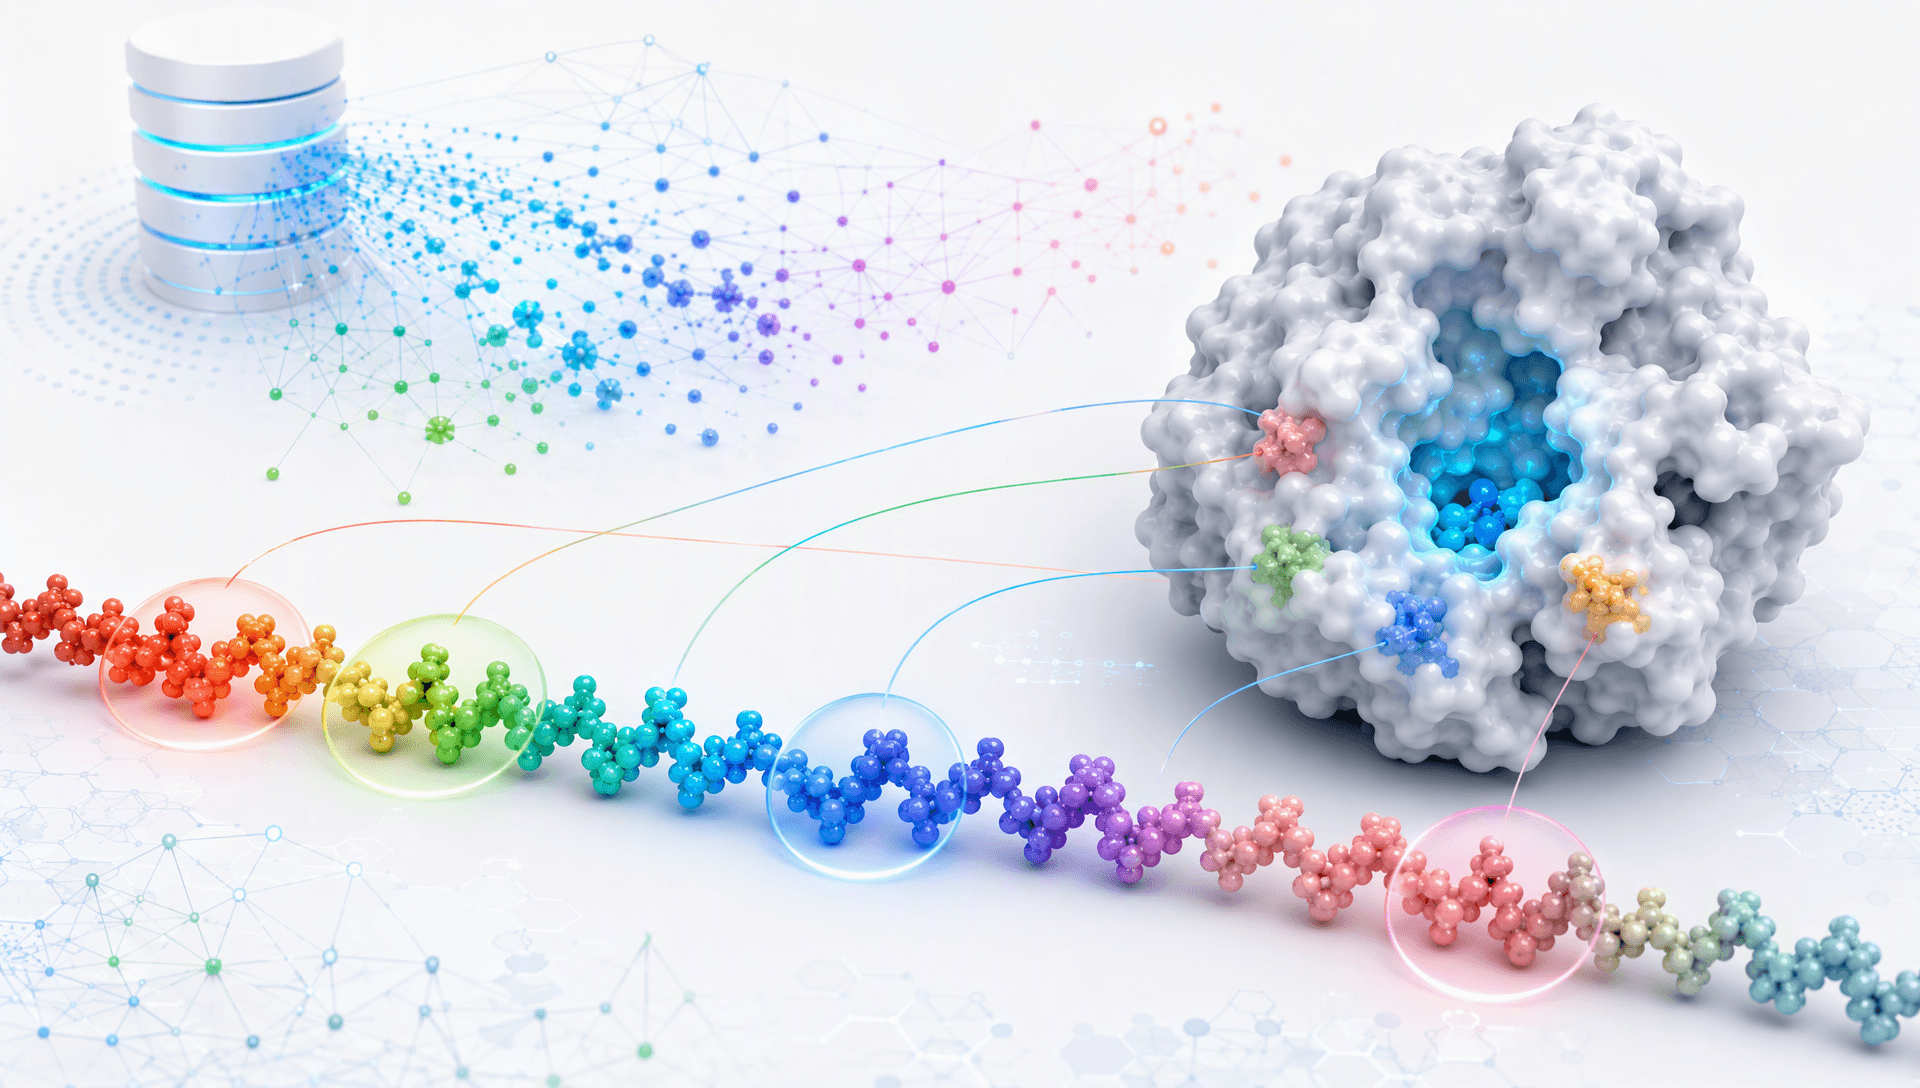
Conserved motifs in a protein sequence point toward a potential enzyme active site
Category: Enzyme Engineering / Computational Biology / Synthetic Biology
In enzyme discovery, the bottleneck is often not a lack of sequences but an excess of candidates. The need to predict enzyme function from protein sequence becomes urgent when metagenomic sequencing, strain discovery, and directed evolution produce thousands of proteins, while the project still needs a much narrower answer: Which candidates might catalyze the target reaction? What substrates could they prefer? Under what temperature and pH conditions might they operate? Which few should enter the first assay plate?
That turns prediction into a resource-allocation problem. A broad family label may be insufficient for substrate selection and assay design. An overconfident prediction can be worse, because it directs experimental time toward the wrong hypothesis. A more useful approach separates enzyme function into questions that can be supported by different evidence.
To predict enzyme function from protein sequence, separate five questions
The first question is whether the protein is plausibly an enzyme. This requires family relationships, conserved motifs, domain context, and a credible arrangement of catalytic residues. The second asks what class of reaction it may catalyze, connecting homologous annotations with curated reaction and enzyme classification records. The third asks about substrate or cofactor preference, which is often harder than assigning a broad enzyme class because a few pocket residues can separate family members with different substrate spectra.
The fourth question concerns operating conditions: optimal temperature, optimal pH, metal dependence, stability, and solubility. The fifth concerns kinetic behavior, such as turnover under a defined substrate and assay condition. As the questions become more specific, sequence alone usually provides weaker constraints, and interpretation depends more strongly on structural context, training-data coverage, and experimental conditions.
This is why attempts to predict enzyme function from protein sequence should not collapse into a single yes-or-no output. EC numbers, GO annotations, pathways, and curated functional descriptions should first be retrieved from authoritative databases rather than presented as facts invented by a model. Computational estimates of active sites, binding sites, conserved residues, or kcat should be labeled Predicted and tied to their intended conditions.
Sequence contains three signal types with different meanings
Family similarity provides the strongest starting point
When a sequence closely matches an experimentally annotated enzyme and the alignment covers both the catalytic core and relevant accessory regions, homology can rapidly narrow the functional space. Similarity alone does not guarantee the same substrate, however. Global identity may obscure a few residues that control pocket size, charge, or cofactor choice, while a local match may say little about the function of the full-length protein.
Conserved motifs suggest catalytic possibilities
Sequence motifs are signatures of protein families, and catalytic residues in many enzyme families follow recognizable patterns. A motif is valuable because it proposes a chemical role for a region; it does not independently prove activity. The motif must still make sense in three-dimensional geometry, surrounding residues must support substrate binding, and the protein must retain a compatible fold.
Local variation drives substrate and property differences
Members of one enzyme family may share a catalytic mechanism while differing at the pocket entrance, first-shell residues, or flexible loops. Those differences can influence substrate range, selectivity, and environmental adaptation. A strong analysis therefore highlights candidate-specific residues in addition to family-wide conservation and labels whether each interpretation comes from experimental knowledge, homologous transfer, or computational prediction.

Substrates and catalytic residues define plausible chemistry inside an active-site pocket
Confidence layers turn resemblance into an experimental priority
Results can be organized into three evidence states. Measured denotes values or annotations grounded in database records or experiments. Predicted denotes inference from homology, sequence models, structural models, or property models. Unknown preserves gaps where support remains inadequate. This prevents strong evidence for one question from masking weak evidence for another.
A candidate may have a reliable family assignment while its substrate preference remains uncertain. Multiple methods may agree on an active-site location even though optimal temperature and kcat are still estimates. The project can then stage validation: use a compact substrate panel to confirm reaction class, measure a temperature and pH window, and only then compare kinetic properties under standardized conditions. Not every candidate needs complete characterization at the start.
A decision-ready result should include candidate identity, plausible reaction class, key catalytic residues, possible substrates or cofactors, environmental properties, an evidence status for each claim, and a minimum validation experiment. It is not simply a ranking table; it is a set of hypotheses that experiments can confirm or refute.
MatwingsVenus™(protein agent)organizes enzyme questions as evidence cards
MatwingsVenus™(晓鹜™)does not need one model to replace databases and experiments. Its role is to determine whether each question belongs to retrieval or prediction. For a raw sequence, the platform follows sequence-first identification: establish identity and homologous context, retrieve existing annotations and measurements, and move to computation only when evidence gaps remain and the user approves the task.
For teams seeking to predict enzyme function from protein sequence, MatwingsVenus™(晓鹜™)can coordinate several levels of analysis. VenusX addresses residue-level questions such as active, binding, and evolutionarily conserved sites. VenusG addresses protein-level properties including stability, solubility, optimal temperature, optimal pH, metal-ion binding, and kcat. Physicochemical calculation can add molecular weight, pI, and related baseline properties. EC numbers, GO terms, and curated functional descriptions remain database-retrieval tasks rather than being blurred into direct model predictions.
This orchestration keeps provenance and status attached to each output. Researchers can see what is Measured, what is Predicted, and what remains Unknown. Compute-intensive predictions retain a user approval point so that the sequence, target property, and intended output can be checked before resources are consumed. That transparency is especially useful when enzyme screening spans several researchers and decision stages.

A microfluidic chip and enzyme assay instruments validate functional predictions
Prediction should directly shape candidate selection and assay design
The final deliverable should go beyond “candidate A has the highest score.” A useful analysis groups candidates according to the development question: those worth testing for the target reaction, those that may offer a different substrate spectrum, those likely to suit the intended temperature or pH window, and those that should be deprioritized because key catalytic residues are absent.
Low-homology, novel, or multidomain proteins require wider uncertainty bounds. Agreement across models can raise priority, but it cannot be rewritten as experimental proof. A predicted kcat must also be interpreted with the substrate, temperature, pH, and assay definition in view. Experiments are not merely a final quality check; they generate the data that update hypotheses, refine screening criteria, and guide the next candidate round.
From sequence labels to testable catalytic hypotheses
The real purpose of efforts to predict enzyme function from protein sequence is to decide what to do next. Identity and database evidence establish a baseline. Enzyme class, catalytic sites, substrate environment, operating conditions, and kinetic properties are then assessed as separate questions. Evidence labels and minimum experiments close the uncertainties that matter most.
MatwingsVenus™(晓鹜™)connects retrieval-first analysis, layered prediction, user approval, and evidence labeling into a traceable research process. For teams working with limited assay capacity, the advantage is not an unexplained automatic answer. It is a disciplined way to convert sequence abundance into a smaller, more informative set of catalytic hypotheses ready for testing.