Protein Domain Analysis: Read Function Through Modular Architecture
Published on October 7, 2026
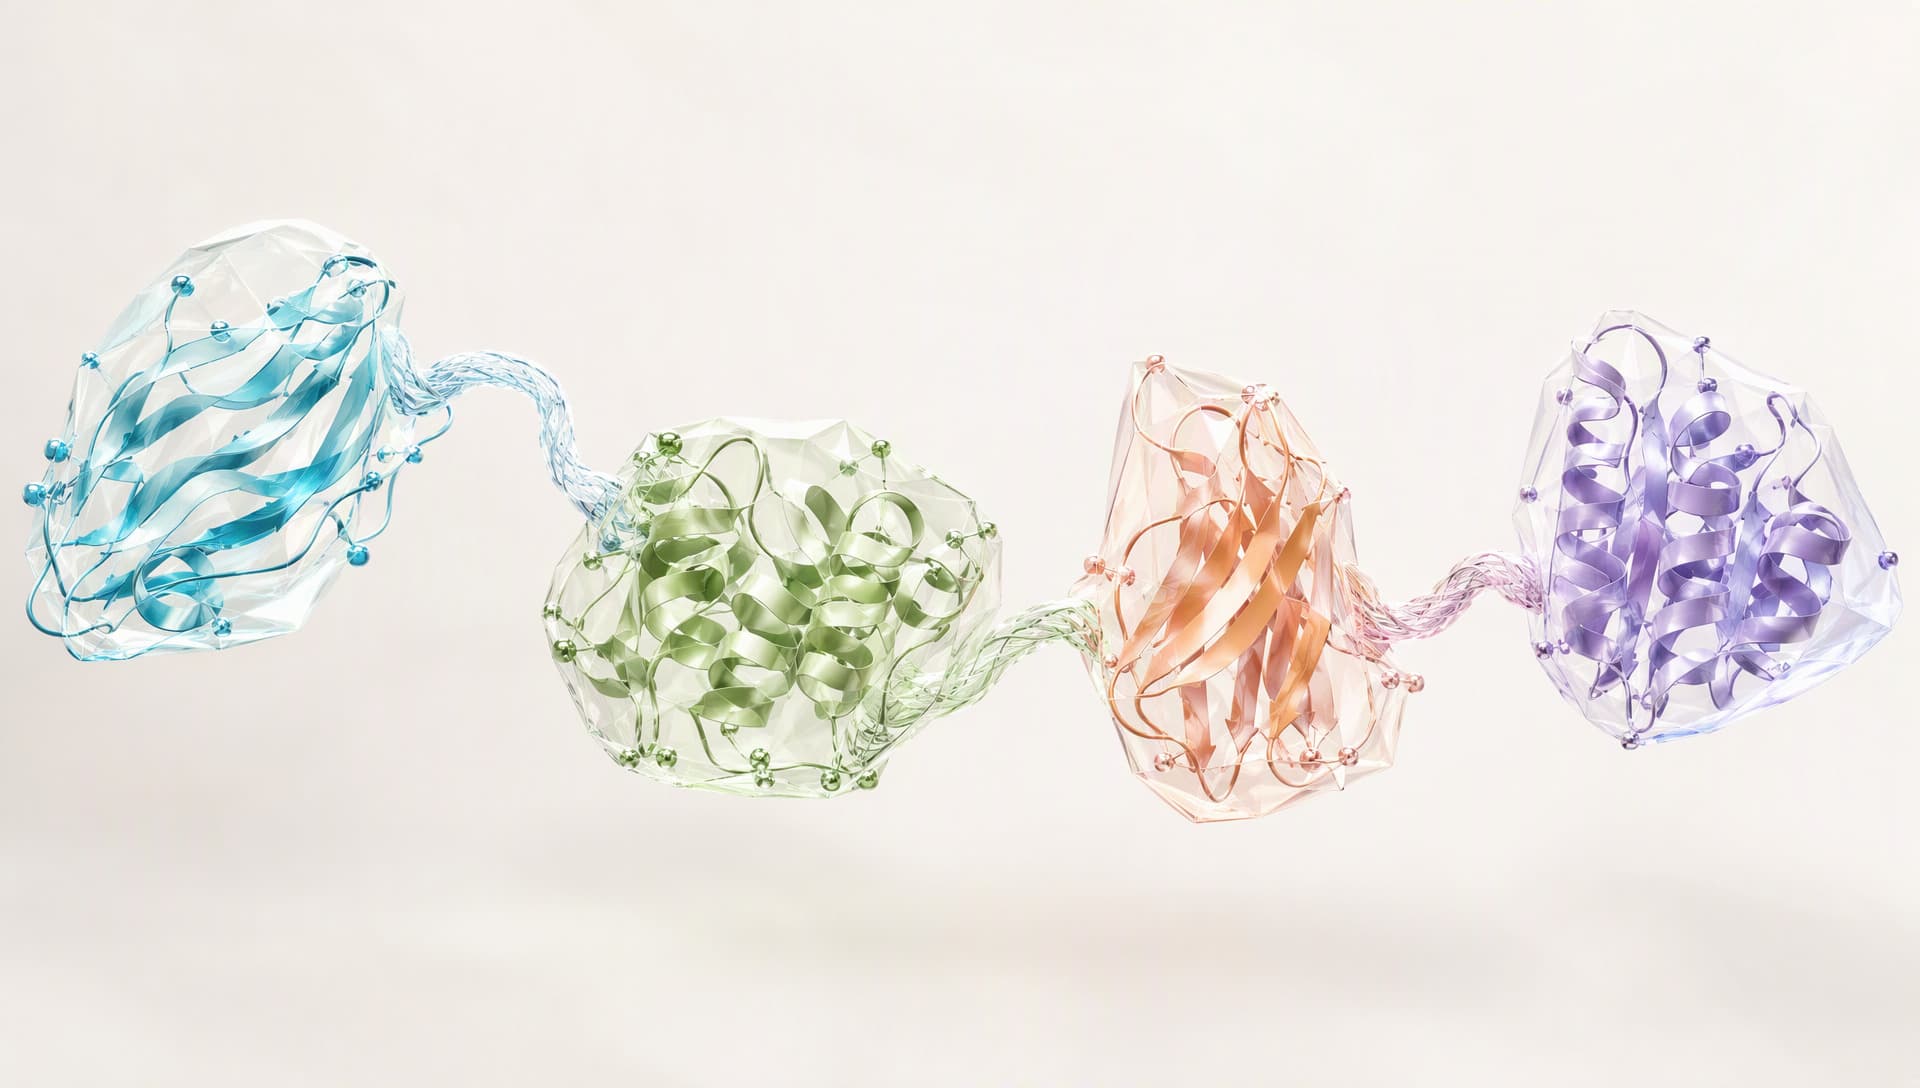
A modular view reveals how complex proteins divide biological work
Protein Domain Analysis Begins by Defining the Module
A domain is commonly treated as a distinct structural, functional, or sequence unit that can occur in different biological contexts. It may perform catalysis, binding, recognition, or regulation, and it may combine with other domains to create new architectures. Because domains can be reused, related modules may appear in proteins whose names and overall functions differ substantially.
A domain is not synonymous with every local feature. A motif is usually shorter and often consists of a small set of conserved residues associated with a specific recognition or reaction pattern. A repeat is a recurring short unit. A functional site focuses on key residues. A disordered region may lack a stable fold yet participate in regulation or interaction. Mixing these categories weakens both functional interpretation and construct design.
The first output of protein domain analysis should therefore be more than colored blocks. It should state what kind of evidence supports each feature, which residues it covers, how it connects to neighboring regions, and which segments remain uncertain.
A Boundary Is an Interpreted Interval, Not a Fixed Cut Line
Domain boundaries often look like simple start and end coordinates, but different resources can disagree. Databases use different sequence models, classification systems, and thresholds. Structural evidence emphasizes independently folding units, while sequence signatures emphasize conserved patterns. Flexible linkers, insertions, discontinuous domains, and low-complexity regions can produce different boundary proposals.
That disagreement does not automatically make one result wrong. A better approach is to treat a boundary as an interval with confidence. Regions supported by several overlapping annotations can be considered a stable core. Extensions supported by only one signature require caution. When sequence and structure evidence diverge, preserve alternative hypotheses and avoid placing an experimental cut in the most uncertain segment.
InterPro integrates signatures from multiple member databases and uses representative domains to reduce redundancy and clarify architecture. Its domain, family, homologous-superfamily, repeat, and site entries represent different annotation types with different inference limits. Identifying what an entry means is often more important than simply reading its color on a viewer.

Consensus across evidence layers strengthens a proposed domain core
Sequence Signatures and Structural Evidence Answer Different Questions
Sequence signatures are effective at recognizing evolutionary patterns and can scan long sequences or large datasets efficiently. Structural evidence is closer to the concept of an independently folding unit and can provide boundary clues where sequence signals are weak. These sources are complementary rather than interchangeable.
A protein domain analysis can begin with authoritative annotations from InterPro and UniProt to identify known families, domains, and sites, then compare those results with fold organization in an experimental PDB structure or an AlphaFold prediction. Agreement between sequence and structure evidence increases confidence. Partial overlap should prompt a closer look at low-confidence coordinates, insertions, linkers, or classification differences.
Measured and Predicted evidence must remain distinct. Experimental structures and curated records provide traceable evidence; predicted models support boundary hypotheses. A visually convincing model does not become an experimental measurement. If no reliable database match exists, the appropriate state is Unknown rather than a forced label for every segment.
Protein Domain Analysis Changes Practical R&D Decisions
A domain map matters because it changes what researchers do next. An expression construct cut through a stable core may fail to fold. A fusion protein that ignores linker length and flexibility may restrict module movement. A mutation interpreted without knowing whether it sits in a catalytic domain, binding domain, or interdomain interface may be assigned the wrong risk.
For construct design, boundaries supported by multiple sources offer better starting points, with reasonable margins around linkers. For functional interpretation, a local domain match should be projected only onto that module, not automatically onto the full protein. For multidomain comparisons, domain type, order, copy number, and missing modules should all be considered because architecture is defined by both the parts and their arrangement.

Clear module boundaries reduce avoidable risk in construct design
Domain evidence can also organize experimental priorities. Regions with stable boundaries and convergent annotations can be expressed first. When several boundary hypotheses remain, a small panel of constructs with different endpoints can test them. Disordered or flexible linkers may be retained, shortened, or examined separately depending on the question. Protein domain analysis is therefore not the end of annotation; it is the beginning of a testable plan.
The MatwingsVenus™(晓鹜™)Workflow Organizes Multisource Domain Evidence
Domain interpretation commonly crosses protein identification, sequence annotation, and structural review. MatwingsVenus™(晓鹜™)provides a conversational database-retrieval interface whose documented capabilities include protein identity, annotation, and structure information from sources such as UniProt, InterPro, PDB, and AlphaFold. Researchers can examine whether those sources support one another around a single question rather than treating every result as an isolated page.
A retrieval-first task can begin by confirming protein identity, continue with InterPro domain and site entries, and then examine fold organization in an experimental or predicted structure. MatwingsVenus™(晓鹜™)keeps evidence states explicit: database measurements or curated records retain Measured provenance, computational results remain Predicted, and missing evidence remains Unknown. This helps prevent one predicted boundary from being presented as settled fact.
When sources disagree, the purpose is not to force a universal answer. The disagreement should be interpreted in the context of the next decision: explaining function, designing an expression construct, or evaluating a mutation. Each objective requires a different level of boundary precision and evidence.
Three Misreadings Can Undermine a Domain Map
First, a domain hit does not define the complete protein function. Multidomain activity depends on module combinations, order, and regulatory context. Second, a boundary coordinate is not automatically an ideal engineering cut site. Secondary structure, linker composition, and terminal stability still matter. Third, multiple annotation tracks do not represent a simple vote; different resources may describe families, superfamilies, domains, or sites at different levels.
A useful report should include protein identity, sequence version, major domains and coordinates, supporting sources, boundary agreement, disordered or linker regions, and implications for the next experiment. Only then does a domain diagram become an R&D decision aid.
Conclusion: Move from a Module Map to a Testable Plan
Protein domain analysis is not the act of coloring a sequence. It explains what each module is, how reliable its boundaries are, how modules are arranged, and how that evidence should change the next decision. Integrating sequence signatures, structural evidence, and database annotation constrains functional inference and improves boundary awareness in expression, fusion, and mutation design.
MatwingsVenus™(晓鹜™)connects InterPro, UniProt, PDB, and AlphaFold information through conversational retrieval while separating Measured, Predicted, and Unknown evidence. For researchers moving from a sequence toward modular interpretation and experimental planning, this evidence-centered approach makes complex proteins easier to frame as clear, reviewable, and actionable questions.