Protein Motif Prediction: From Short Matches to Functional Evidence
Published on September 20, 2026
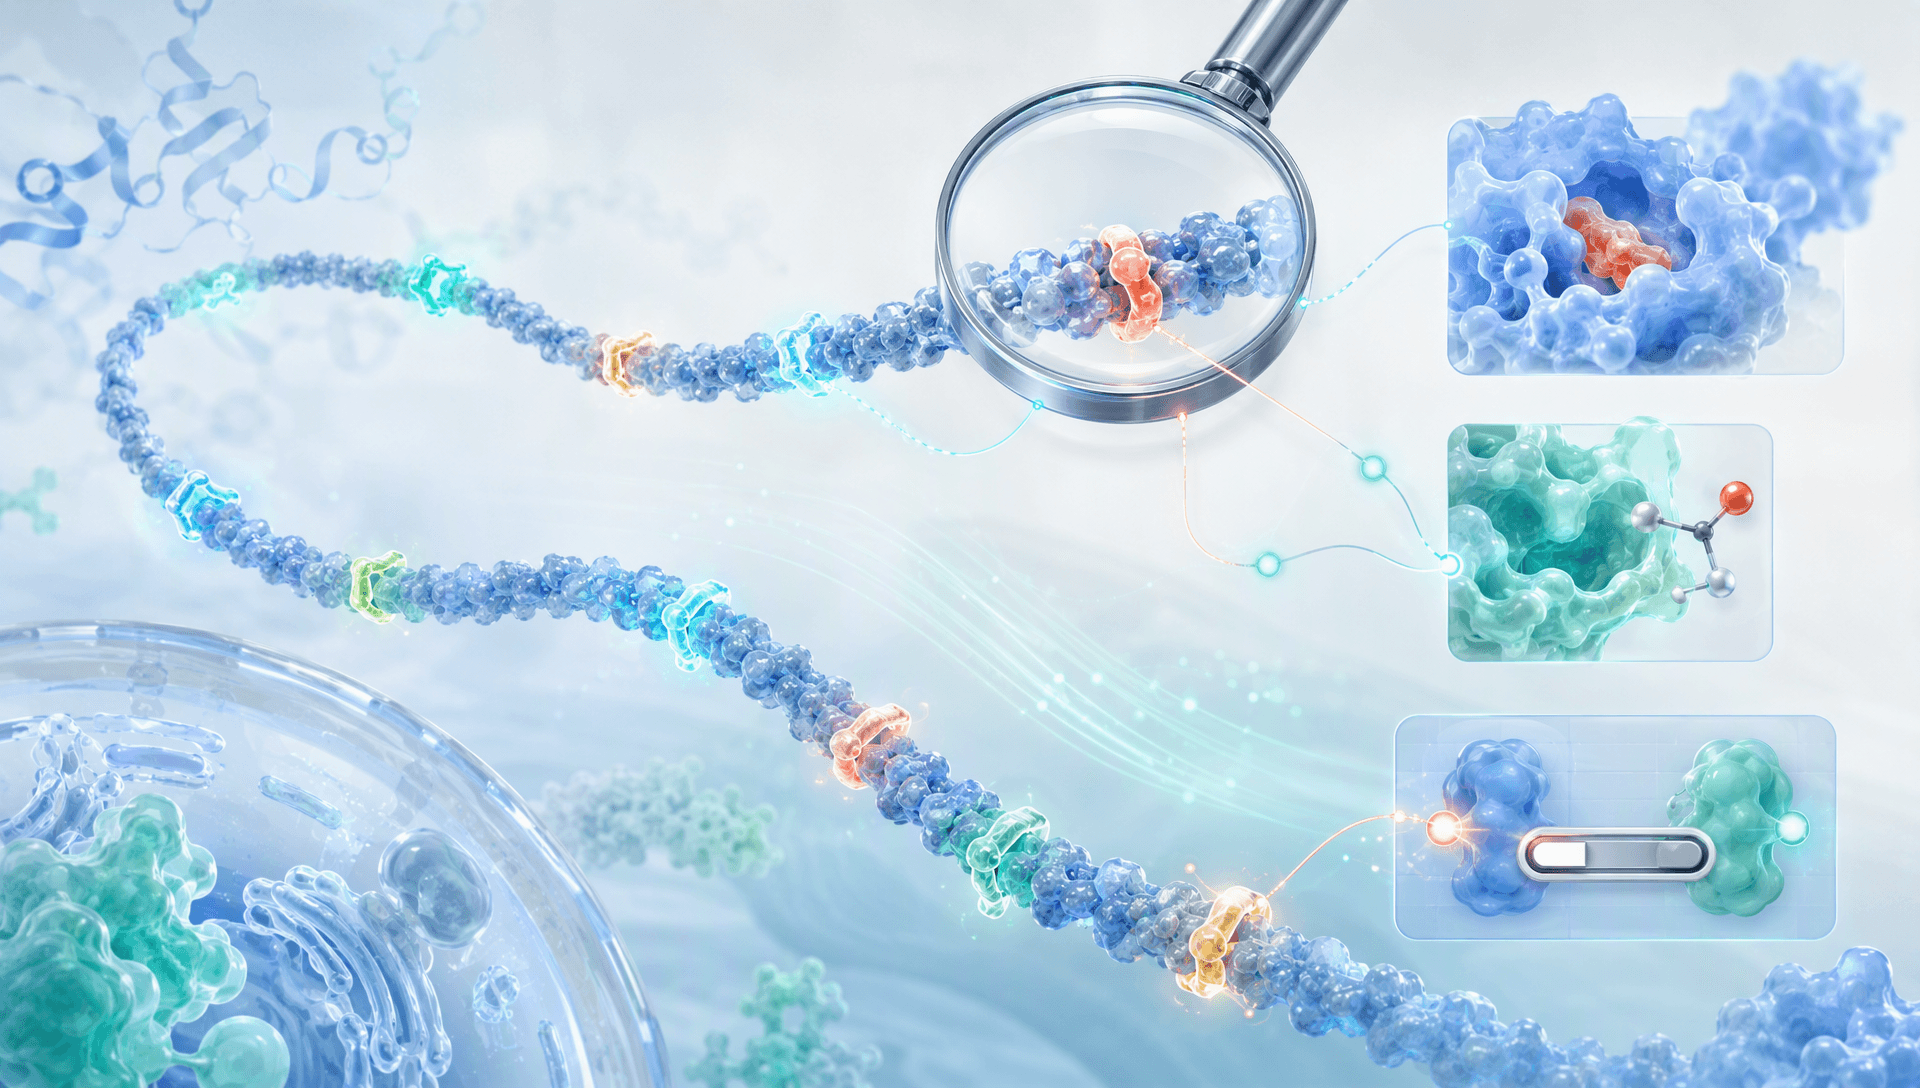
Short sequence signals along a protein connect to binding, modification, and regulatory functions
Protein motif prediction is difficult because motifs are short and non-unique
A motif is a local sequence feature associated with biological meaning. It may indicate catalytic residues, a protein-binding interface, a post-translational modification site, or a localization signal. Unlike a larger domain, a short linear motif can span only a few neighboring amino acids and need not form an independently folded unit, yet it may operate as a compact regulatory switch.
That compactness creates a statistical problem. A pattern containing a few required residues and several permissive positions can occur by chance in a long sequence. Longer proteins and larger pattern libraries naturally produce more candidates. Protein motif prediction should therefore never convert a pattern match directly into a confirmed functional site. A useful output distinguishes experimentally validated instances, database-supported candidates, and computational matches.
Defining the biological question reduces noise. A modification-site search should consider whether the relevant enzyme can occur in the same cellular setting. A binding-motif search needs a plausible partner and structural accessibility. A mutation study must also avoid damaging the overall protein fold. The same motif class can require different validation strategies in different contexts.
What patterns, profiles, and rules contribute
Resources such as PROSITE represent biologically meaningful sequence features with patterns and profiles. A pattern resembles a sequence rule with permitted variation and is useful when a few positions carry strong information. A profile combines preferences across many positions and can capture more distributed family features. Additional rules may encode functionally or structurally critical residues and improve interpretation.
These representations are not simply ordered from weak to strong. A short pattern may be sensitive but return many candidates. A profile can absorb broader family variation but remains dependent on its training set and thresholds. Contextual rules improve discrimination but may exclude atypical members. The goal is not to find one universally correct descriptor; it is to understand what each descriptor detects and what it can miss.
When reading a hit, researchers should inspect coverage, required positions, repeated occurrences, taxonomic scope, and whether the original signature was intended to recognize a family, domain, or functional site. A match becomes interpretable only when its definition and applicable scope travel with it.
Protein motif prediction needs context to reduce false positives

Many short matches pass through biological filters before a small candidate set remains
Short linear motifs are often degenerate: several amino acids can vary while a function is retained. As a result, regular-expression scanning alone is prone to overprediction. An authoritative resource focused on eukaryotic linear motifs explicitly warns that many putative matches will be false positives and uses taxonomy, cellular compartment, evolutionary conservation, and structural features to improve predictive power.
The first filter is biological accessibility. A strong sequence match buried inside a stable folded core may not reach its partner. Short segments in disordered regions or flexible loops are often more available for transient regulation, but disorder alone does not prove function. The second filter is cellular context: a candidate motif, its modifying enzyme, and its binding partner must have a plausible opportunity to meet.
The third layer is evolutionary and family evidence. Conservation among relevant species or homologs can raise a candidate’s priority. However, regulatory motifs can evolve rapidly, so demanding strict conservation across an entire family may discard lineage-specific signals. A fourth layer considers competing explanations: low-complexity regions, transmembrane segments, signal peptides, or other structural constraints may give a matching sequence a different role.
Protein motif prediction is consequently better expressed as a ranked evidence set than a binary answer. Displaying pattern support, accessibility, conservation, cellular context, and existing annotations side by side makes the prioritization transparent.
Move from candidate lists to a minimal validation set

Candidate motifs progress through annotation checks and structural review into mutation and binding experiments
A high-quality protein motif prediction workflow should lead directly to experimental design. For a high-priority candidate, researchers can disrupt essential residues while selecting controls that preserve local charge, hydrophobicity, or structure as far as possible. A proposed binding motif can be tested by comparing interactions of wild-type and mutant proteins. Modification or localization hypotheses require assays aligned with the proposed mechanism.
A phenotype change after mutation is not sufficient on its own. If the mutation also lowers expression, stability, or correct folding, the observed effect may come from global damage rather than specific motif disruption. A minimal validation set should therefore include protein abundance or folding controls and, where feasible, partner-dependence or position-swap tests.
Negative results are informative as well. They may show that a candidate was an incidental match, or that the selected cell state, partner, or stimulus was unsuitable. Recording conditions and contradictory evidence allows the next round of prioritization to improve instead of treating one negative observation as proof that a motif cannot exist.
MatwingsVenus™(晓鹜™)turns motif screening into an evidence chain
Motif research often moves repeatedly among sequence verification, database annotation, structural context, and functional-site analysis. The official MatwingsVenus™(晓鹜™) website lists intelligent conversation, protein sequence analysis, structure prediction, and database retrieval among the platform’s capabilities, making it relevant for organizing these connected research tasks.
For an input sequence, researchers can first use MatwingsVenus™(晓鹜™) to organize identity checks and retrieve existing functional-site records. Sequence analysis and structural information can then address regions that remain unexplained. Database evidence, Predicted candidates, and Unknown regions should remain separate so that retrieval, model judgment, and research hypotheses are not conflated.
A focused request can ask MatwingsVenus™(晓鹜™) to organize candidates around a defined question, such as which short segments combine a pattern match, surface accessibility, and plausible partner context. The platform can connect retrieval and analysis, but whether a specific motif database, scanner, or graphic is available directly should be confirmed from the current interface and actual output. Every prediction still requires experimental validation.
A publishable result explains why a candidate deserves attention
A reproducible report should retain the input sequence version, residue numbering, pattern or profile version, thresholds, taxonomic and cellular context, accessibility assessment, and evidence for and against each candidate. Protein motif prediction should also distinguish a curated experimental instance from a new candidate that merely matches a known signature.
Not every match needs to appear in one figure. A clear presentation can locate candidates on the full sequence, expand the contextual evidence for top-ranked segments, and then connect those segments to validation experiments. The conversational task organization emphasized by MatwingsVenus™(晓鹜™) can keep these steps in one research context, giving every prioritization choice a traceable rationale and a next action.
Conclusion: make short sequence signals withstand biological questions
Protein motif prediction should not maximize the number of highlighted fragments; it should continuously remove incidental matches. Patterns and profiles discover signals, taxonomy, compartment, conservation, and structural accessibility rank them, and mutation plus functional assays validate them. By using MatwingsVenus™(晓鹜™) to connect database retrieval, sequence analysis, and structural information, researchers can turn scattered matches into function hypotheses with explicit evidence levels and practical validation routes.