How a Scientific Research Agent Rebuilds the Protein R&D Workflow
Published on September 20, 2026
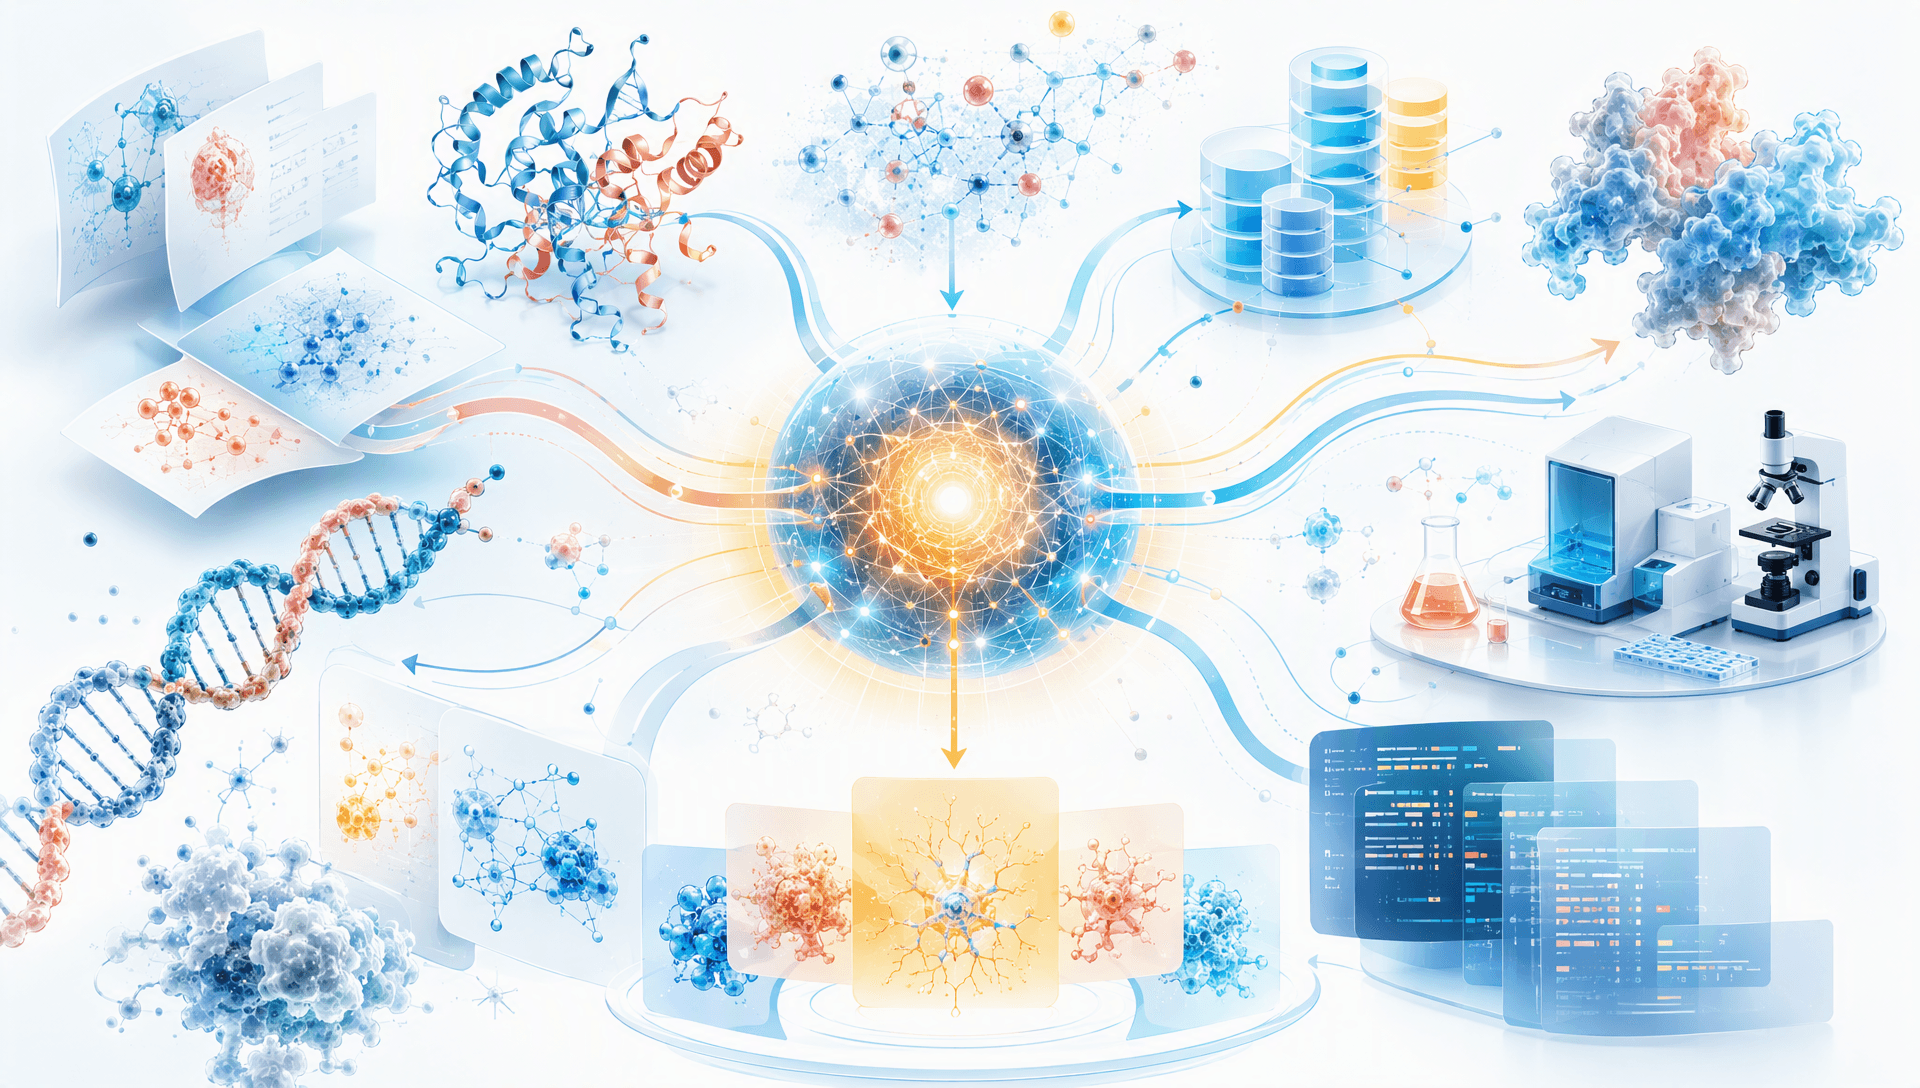
A connected research hub where evidence, tools and experiments converge
Category: AI for Science | Life Sciences | Protein R&D | Intelligent Research Workflows
Many protein R&D projects do not stall because a model is missing. They stall at the handoffs. Findings from a literature review fail to become design constraints. Database records and model predictions are mixed together. Computational candidates arrive without experimental acceptance criteria. Wet-lab feedback then struggles to make its way into the next design cycle.
The shift is being driven by more than model progress. Scientific data and specialized tools are multiplying, coordination costs are rising, computational outputs need faster experimental feedback, and teams face greater pressure to preserve provenance and human accountability. As a result, the center of gravity is moving from generating an answer to orchestrating an auditable task chain. A scientific research agent can understand the objective, select tools, retain intermediate evidence, request expert judgment at critical points and adapt the next step to new results. The practical promise is not “science in one click,” but a process that a team can inspect, pause and resume.
The scientific research agent is moving from answers to orchestration
A conventional AI assistant usually turns one prompt into one response. That is useful for explaining a concept or drafting an initial hypothesis, but research must also account for entity identity, data provenance, method applicability, parameter choices and validation criteria. A reliable scientific research agent therefore needs to know when to query a database, when a predictive model is appropriate and when the workflow must stop for a researcher’s approval.
This changes the evaluation criteria. A fluent response is not enough. Teams need to ask whether a claim comes from an experimental record or a computation, whether tool calls and parameters are traceable, and whether expensive or consequential actions retain human oversight. When those elements are explicit, collaborators can review conclusions, diagnose failure and carry knowledge into the next experiment.
MatwingsVenus™(晓鹜™) applies this logic to protein R&D by routing each research intent before invoking a capability. An open-ended question can move into deep research; a known protein can be checked against authoritative databases; missing information can lead to functional-site or protein-property prediction; and discovery, engineering or de novo design follow different task paths. The purpose of this modular structure is not to accumulate tools. It is to prevent retrieved facts, predicted properties and newly generated designs from being treated as the same kind of evidence.
Evidence layers should come before model calls
In protein research, the statement “this protein may be more stable” can reflect an experimental measurement, a curated annotation, a model output or an untested hypothesis. If those layers are not separated, a precise-looking candidate ranking can conceal substantial decision risk.
MatwingsVenus™(晓鹜™) follows a retrieval-first approach. For a known entity, the workflow first looks for sequence, structure, function, variant or experimental records in authoritative sources. A raw sequence is identified before the system interprets properties, structure or design options. Data-bearing conclusions are differentiated as Measured, Predicted or Unknown. This does not remove uncertainty; it puts uncertainty in the right place.

Database evidence passes through checkpoints before prediction and design
Evidence status also determines the next action. Reliable experimental records can reduce redundant computation. An empty database result might justify a prediction, but only after the researcher decides that the additional work is worthwhile. If a prediction will influence synthesis or experimental spending, its conditions and validation plan should travel with the result. The scientific research agent is valuable not because every action becomes automatic, but because the rationale for continuing becomes visible.
Protein R&D needs a workflow that can branch
A usable workflow should not send every project into the same model. Protein R&D can be organized around four linked decisions.
First, define the object and the objective. A protein name, database identifier, sequence or structure file determines how identity should be established. Goals such as stability, activity, expression or binding must be paired with experimental conditions, protected regions and a measurable acceptance criterion.
Second, establish the evidence baseline. Resources such as UniProt and PDB can provide known sequence, structure and annotation data, while other authoritative databases can add variants, pathways, kinetic information or clinical context. In MatwingsVenus™(晓鹜™), protein database querying serves as an upstream evidence layer for several downstream tasks, so prediction and design do not need to begin from a blank page.
Third, choose the correct branch. Unknown properties can move into functional prediction. A search for natural candidates should explore existing sequence and structure space before heavier mining is considered. Engineering an existing protein requires a wild-type baseline and protected functional sites before single- or multi-mutation candidates are assessed. De novo design is appropriate only when the objective genuinely requires a new scaffold, followed by sequence design and folding validation. MatwingsVenus™(晓鹜™) organizes deep research, database querying, function prediction, protein discovery, protein engineering and de novo design as distinct but connected capability modules.
Fourth, validate the candidates. Prediction scores can support filtering and ranking, but they are not measurements of affinity, activity or project success. Expression, purification and functional assays still determine whether a candidate satisfies the research objective. Here, the scientific research agent carries context and orchestrates the handoff; it does not certify an experimental outcome.
Human approval is a quality-control feature
Life-science computation can carry meaningful cost, data sensitivity and experimental consequences. Function prediction, structure mining, mutation assessment, generative design and simulation should not run invisibly. A more robust model is to define inputs, parameters, expected outputs and stop conditions, then require a researcher to approve heavy computation. The same checkpoints can be used to revise or halt a task when evidence conflicts or the scope changes.
This human-in-the-loop design preserves both efficiency and accountability. MatwingsVenus™(晓鹜™) places confirmation points before computationally intensive actions and retains transparent failure information. For academic labs, this can help students, computational scientists and experimentalists work from the same record. For R&D organizations, it can reduce context loss across roles and make each additional investment easier to justify.

Design candidates move through experiments and feed results back into decisions
Trend impact: cumulative iteration becomes a reusable R&D asset
A single prediction can generate candidates, but R&D efficiency comes from learning across cycles. Which constraints worked? Which candidates failed? Which assay conditions changed the interpretation? Which data should influence the next round? If these answers remain scattered across chat histories, spreadsheets and personal computers, each cycle begins by rebuilding context. As the focus shifts from isolated models to continuous task chains, research records become inputs to the next decision rather than static archives.
Once a scientific research agent connects goals, evidence, tools, approvals and results, failure can become reusable information. A functional region may need protection, a model may only apply to a specific input type, or an experimental route may require additional data. This accumulation matters in protein engineering because the candidate space is large and every synthesis and test consumes real resources.
A scientific research agent does not guarantee a better scientific conclusion. Data quality, model domain, parameter settings and experimental design still require expertise. When evaluating a platform, the useful questions are therefore not limited to “Can it produce the best answer at once?” Teams should also examine support for authoritative retrieval, evidence labels, task routing, human approval, transparent failure and a validation loop. These restrained design choices are what make a workflow reusable.
Implementation advice: start with one verifiable task
A team does not need to begin with its most complicated program. A better starting point is a protein task with a clearly identified object, a measurable objective, organized baseline data and explicit experimental acceptance criteria. Build a minimum loop of retrieval, decision, computation and validation, then observe which actions merit automation and which checkpoints require expert control.
MatwingsVenus™(晓鹜™) brings distributed protein R&D capabilities into a bounded, conversational path. For a team exploring a scientific research agent, the next step is not to delegate every decision to AI. It is to test the workflow on a real project and ask whether evidence becomes clearer, collaboration becomes smoother and each experimental cycle informs the next design more effectively.